Predictive Maintenance vs. Preventive Maintenance: Why the Difference Shows Up on Your Margin, Not Just Your Glossary
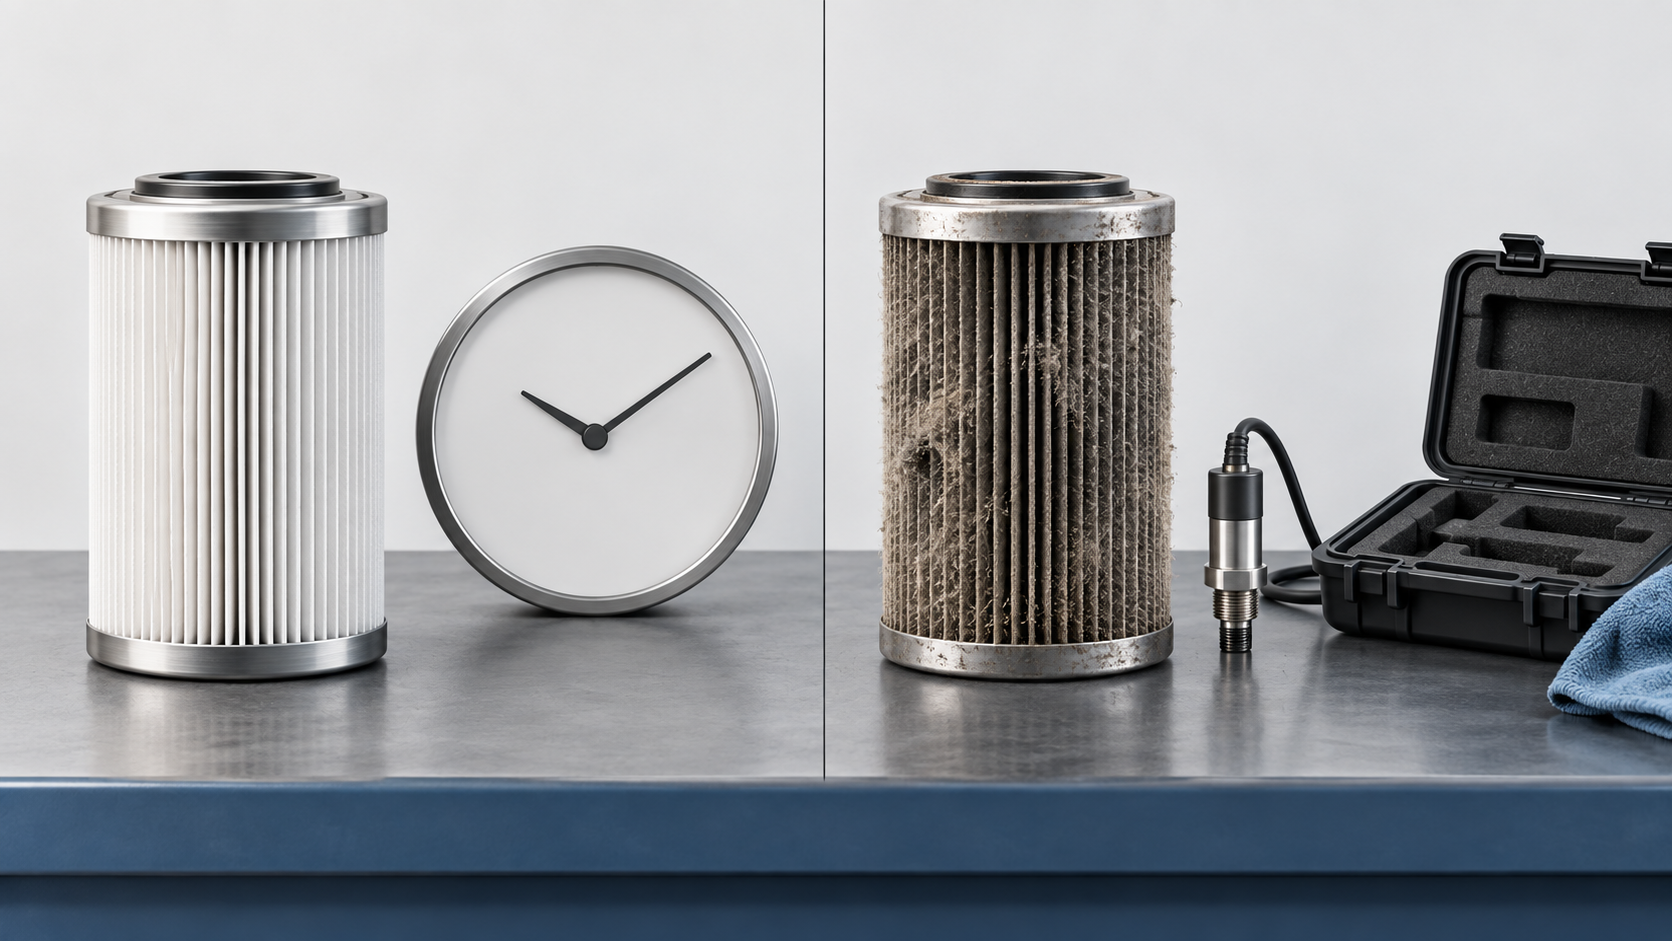
"We change the filter every 90 days whether it needs it or not." That's preventive maintenance, and it's costing more than anyone tracks, this is where predictive maintenance changes the math, and where the difference actually shows up on a P&L.
"We've Always Done It on a Schedule"
An asset manager we talked to put it bluntly: "I don't know if the pump needs service. I know it's been 90 days."
That's preventive maintenance in one sentence. A calendar decides. Not the machine.
Predictive maintenance flips that. The machine's condition decides, through vibration, temperature, pressure, current draw, or another time-series signal, and the calendar becomes irrelevant.
Both strategies aim at the same outcome: fewer surprise failures. But they get there through opposite logic, and that difference compounds into real dollars across a fleet.
The Textbook Definitions
Worth stating plainly, because the terms get blurred constantly:
- Preventive maintenance is scheduled. Tasks happen at fixed intervals, daily, monthly, every 500 operating hours, regardless of the asset's actual condition. IBM frames it as maintenance performed on a routine schedule to reduce the likelihood of failure.
- Predictive maintenance is condition-based. Maintenance happens when the data says it's needed, not when the calendar says so. As Advanced Technology Services describes it, preventive maintenance relies on predetermined service intervals, while predictive maintenance uses equipment condition and performance data to determine when maintenance is actually needed.
- Reactive maintenance, the third leg most comparisons include, is fixing things after they break. Prometheus Group's breakdown notes reactive maintenance offers maximum asset utilization right up until the point of failure, then the cost curve inverts fast.
Most facilities run all three, whether they mean to or not. The real question isn't which one is superior in a textbook. It's which one is running which asset, and whether that's a deliberate decision or an accident of history.
Where the Difference Actually Lives: Not the Definition, the Dispatch
Asset managers don't lose margin to bad definitions. They lose it to what the definition triggers.
Preventive maintenance triggers a truck roll or a technician dispatch on a fixed date. Every time. Whether the asset needs it or not. That's the cost of the schedule: labor and parts spent on assets that were fine, plus downtime that didn't need to happen.
Predictive maintenance triggers a dispatch only when a condition signal says something is drifting. In theory, that's fewer visits and better-targeted ones. In practice, it only works if someone can actually see the condition signal, understand it, and act on it before the failure, not after.
That's the part the glossary comparisons skip. The gap between preventive and predictive isn't philosophical. It shows up as:
- Truck rolls that didn't need to happen, a technician sent on schedule to an asset that was healthy.
- Truck rolls that happened too late, a technician sent reactively, after the tenant or customer already found the problem.
- Interventions nobody can verify, a technician resets something, closes the ticket, and no one can prove whether the actual issue was resolved or just masked.
A connected-assets deployment that closed this gap saw 75% fewer site visits, not by predicting every failure perfectly, but by combining telemetry, history, and prior interventions so a truck only rolled when the data actually called for it, and the technician showed up knowing what to prepare for.
Why Predictive Maintenance Fails Before It Starts
Here's what most predictive maintenance pitches leave out: you can't build a reliable prediction on top of patterns nobody has validated.
Teams jump straight to "build the model" and skip the step where they confirm which anomalies actually preceded which failures, which interventions actually worked, and which alerts were noise. Without that groundwork, predictive maintenance becomes another dashboard nobody trusts.
That's the argument we make in why predictive maintenance pilots stall before they ever reach prediction, exploration has to come first. You investigate, you validate the pattern under supervision, and only then does it earn a place in an automated alert or a predictive model.
It also explains why raw sensor data alone doesn't get you there. As we cover in IoT sensors alone won't give you predictive maintenance, the sensors can be perfect and the program can still stall, because nobody connected the signal to the operational context that makes it meaningful.
The Anomaly Was in the Data. Nobody Saw It.
This is the pain that sits underneath most "we should go predictive" conversations: the pattern was there. It just never surfaced to the person who could act on it.
Raw time-series data holds the anomaly days or weeks before failure. But it's buried in millions of points across dozens of tags, and unless someone is actively watching that specific asset at that specific moment, it stays buried until the asset trips, or worse, until a tenant or customer notices first.
Fleet-wide, this is what makes visibility the actual bottleneck, not the sensors. A two-person team supervising 400+ heat pumps can't manually eyeball every trend line. They need the anomaly to come to them, a logic-check surfaces it and notifies the right person the moment it appears, instead of leaving it sitting in a historian nobody queried that day.
Proving the Intervention Actually Worked
There's a second gap that rarely makes it into predictive-maintenance comparisons: even when a technician does intervene, correctly, on the right condition signal, most teams still can't prove the fix worked.
The ticket closes. The truck leaves. Nobody goes back and checks whether the vibration signature actually normalized, or whether the same fault resurfaces in three weeks under a different symptom. That's not a predictive-maintenance problem or a preventive-maintenance problem, it's a validation gap that sits downstream of both.
Closing it means comparing before-and-after condition data automatically, and comparing performance across sites and peers so a recurring issue at one location doesn't stay invisible to the rest of the fleet.
Asking the Question Shouldn't Take 11 Days
Somewhere between preventive and predictive, there's a step nobody puts on the maintenance-strategy diagram: the investigation.
"Why did pump B7 trip last Tuesday" sounds like a simple question. In practice it can turn into an email chain across three teams, because the work order lives in one system, the machine data in another, and the maintenance history in a technician's memory. We've written about that exact chain in what an IoT predictive maintenance case study leaves out and in why your pump trip investigation takes 11 days.
A deterministic, explainable answer to that question, cross-referenced automatically against maintenance logs, is what turns monitoring, which tells you what happened, into something that tells you why. That distinction is the subject of monitoring tells you what happened, here's what it takes to find out why.
So Which Strategy Should You Run?
Not a trick question, and not an either/or. Most fleets need all three tiers, applied deliberately:
- Reactive for low-criticality assets where failure is cheap and safe.
- Preventive for assets with well-understood wear patterns and low monitoring cost.
- Predictive for critical, expensive-to-fail assets where condition data is available and the cost of a truck roll or downtime hour is high.
The asset managers we work with aren't choosing predictive maintenance because it's the newer term. They're choosing it because the truck-roll math stops working at scale under a pure preventive model, and because they're tired of technicians resetting a fault with no way to confirm it's actually fixed.
Getting from preventive to predictive isn't a single leap. It runs through exploration and validation first, a loop we describe in the real bottleneck in industrial IoT predictive maintenance.
FAQ
What is the main difference between predictive and preventive maintenance?
Preventive maintenance runs on a fixed schedule regardless of asset condition. Predictive maintenance runs on the asset's actual condition, using time-series signals like vibration or temperature to decide when service is needed.
What are the 3 P's of maintenance?
Not a standard industry term, but people typically mean the three foundational strategies: preventive, predictive, and (reactive as the implicit fourth), planned scheduling, condition-based response, and run-to-failure repair.
What are examples of predictive maintenance?
Vibration analysis on rotating equipment, thermal imaging on electrical panels, oil analysis on gearboxes, and condition-based alerts triggered by anomalies in time-series sensor data before a failure occurs.
What are the four types of preventive maintenance?
Common breakdowns include time-based (fixed calendar intervals), usage-based (triggered by operating hours or cycles), failure-finding (testing protective devices), and condition-directed checklist tasks performed regardless of measured condition.
Is predictive maintenance always better than preventive maintenance?
No. Predictive maintenance requires condition data and the ability to interpret it reliably. For low-criticality assets or where monitoring costs exceed the risk of failure, scheduled preventive maintenance can still be the right call.
Why do predictive maintenance programs stall?
Most stall because teams try to build a predictive model before validating which patterns actually preceded past failures and which interventions actually worked. Exploration and validation have to come before prediction.